Executive Summary
A solo product build that turns prospect discovery into a personalized maturity report using three cooperating AI agents. I owned the PRD, domain model, architecture, specs, and implementation, with Claude executing from my specs; every architectural call and correction was mine.
After proving the assessment-to-report loop with a small prototype, I rebuilt the full-stack product over about three months of spec-driven development. A Datadog version for qualifying prospects is under discussion with partner and product teams, not yet built.
Challenge
Sales and partner teams qualifying leads for observability, AIOps, and security tooling typically rely on unstructured discovery calls: slow to scale, vary from rep to rep, and give the prospect nothing back.
One product, two audiences:
- Seller: a structured, repeatable way to qualify leads, based on the prospect's own answers and researched company context, not just company size and industry.
- Buyer: something useful in return, a personalized maturity report across five domains (observability, AIOps, AI app observability, ML/foundation model ops, security).
The bet: a well-designed assessment with an insightful report gives the seller better-qualified leads and the buyer a useful report, from the same interaction.
Approach
Used spec-driven development deliberately over open-ended "vibe coding": specs define what the system does, code defines how, and the spec stays the reference.
Design constraints: four, self-imposed and set up front:
- Runs on one machine: a local model by default (Ollama/llama3.2), switchable to Anthropic or OpenAI with one setting, no paid AI services needed.
- No hard-coded domain data: pillars, questions, and personas are database rows, never code.
- Executable specs: working instructions for the build, not wish-list documentation.
- Async, typed, tested: async FastAPI, typed TypeScript (no
any), and pytest for routes, sign-in, scoring, and agent fallbacks.
Spec structure: eight versioned files, each scoped to one build task, so Claude Code loaded only what it needed. Specs were read-only during a task; one that looked wrong was flagged, not quietly reinterpreted.
System design:
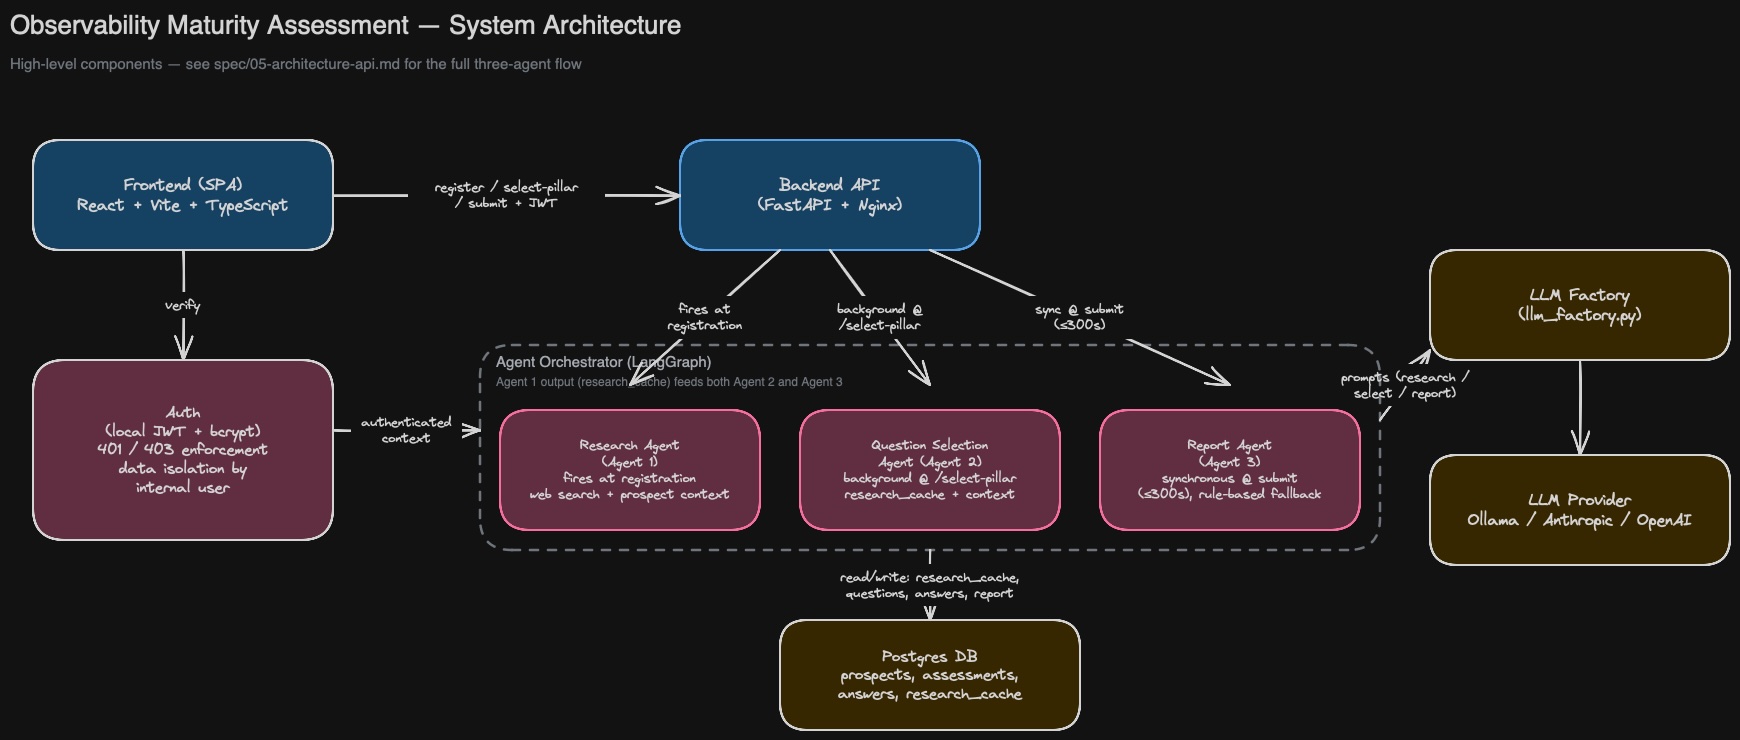
- Three roles: Prospect, Internal User, Admin.
- Five-stage journey: Landing → Pillar Select → Research Summary → Assessment → Report.
- Three LangGraph agents: research builds a company profile, question selection tailors the assessment, and the report agent scores answers and writes the report.
- One model gateway: every model call goes through one function, with per-agent overrides.
Execution
The build moved fast once specs were in place; the hard, ongoing work was keeping specs, diagrams, and code in agreement. The hardest parts:
- Drift: small code decisions (which page calls which endpoint, whether to wait for a result or check back) quietly got ahead of the specs. Fixed with repeated reconciliation passes, checking every related file for each reported gap, not just the one flagged.
- Specs that outgrew the original files: extending the domain model or architecture took care not to repeat content.
- Keeping everything in step: Claude Code skills, the pytest suite, and the Excalidraw diagrams all had to match the spec and code, not just each other.
- Correction discipline: when Claude Code reported a mismatch, the fix was always to update the spec to match what the code did, never to "clean up" the code toward a nicer design. That took explicit rules, not just good intentions.
Outcome
A working, standalone product: full prospect-facing assessment flow, an internal dashboard for accounts/prospects, an admin panel for pillars/questions, and the three agents producing a structured report (executive summary, strengths, gaps, next steps). It all runs locally with Docker Compose, no outside services needed.
Built to extend toward production, not as a finished product:
- New pillars and questions still need only database rows; that constraint held.
- Switching to a hosted frontier model is one setting, with no local-only shortcuts to undo.
- Next chapter: the Datadog version.
Reflection
As much about working responsibly with an AI coding agent as about building the platform. Carrying forward:
- Define the user journey first, more rigorously. I designed the flow early, but I'd now settle every screen transition and edge case before writing any spec; most reconciliation passes traced back to open journey questions.
- Spec-driven development works, but keeping specs accurate over time is still an open problem for me: workable, not solved. Treating drift as a bug, not a documentation chore, was the most valuable habit I built.
- Next, learn to scale it: build skills, use agents (testing, UI consistency checks), and set up loops so a whole spec update ships smoothly and faster.